How to Audit document.currentScript Inline Rendering for SEO
Is document.currentScript inline rendering safe for SEO? I measured what rendered, raw-HTML and Markdown readers see, plus CLS and the cost of 1,000 scripts.

TL;DR — document.currentScript.replaceWith(value) is a clean way to drop dynamic text into static HTML, and it causes no layout shift, but the value only exists after JavaScript runs. In my tests a raw-HTML reader saw “Plan costs per month”, this site’s own Markdown renderer saw the same hole, and a naive tag-stripper leaked the script source into the text. Use it for a copyright year, never for a price, version or claim you want indexed or quoted.
document.currentScript inline rendering is a technique where a tiny inline script element finds itself through document.currentScript and calls replaceWith() to swap itself for a computed value, so the output appears exactly where the script sat in the HTML.
What Is document.currentScript Inline Rendering?
Lean Rada described the trick in a note on inline rendering with currentScript, and Simon Willison’s write-up added a helper that makes it read like a template language:
<script>$ = (...n) => document.currentScript.replaceWith(...n)</script>
<p>Build: <script>$("v" + 42)</script></p>
There is no placeholder element and no ID. The helper is defined once, and each call replaces its own script element. I like it. It is the smallest dynamic-text mechanism the platform offers.
That elegance is also the SEO problem. The HTML your server sends does not contain “v42”. It contains a program that produces “v42” in a browser. Whether that matters depends entirely on who is reading the page, which is the question the next section answers with measurements.
What Do Googlebot, AI Crawlers and Markdown Fetchers See?
I built a pricing page with two inline replacements (a computed price and the current year) plus one static control line, then read it four ways. The browser run used Chromium through Playwright; the Markdown run used the same htmlToMarkdown serializer that generates this site’s .md renderings.
| Reader | What it saw for the line “Plan costs ___ per month” |
|---|---|
| Rendered DOM (browser, Googlebot-style) | Plan costs $3 per month. Copyright 2026. |
| Raw HTML, scripts removed | Plan costs per month. Copyright . |
| Naive tag-strip, scripts kept as text | Plan costs document.currentScript.replaceWith("$"+(0.75*4)) per month. |
| This site’s HTML-to-Markdown serializer | Plan costs per month. Copyright . |
The static control line (costs $3 per month) survived in all four. Only the script-produced text disappeared, or worse, leaked.
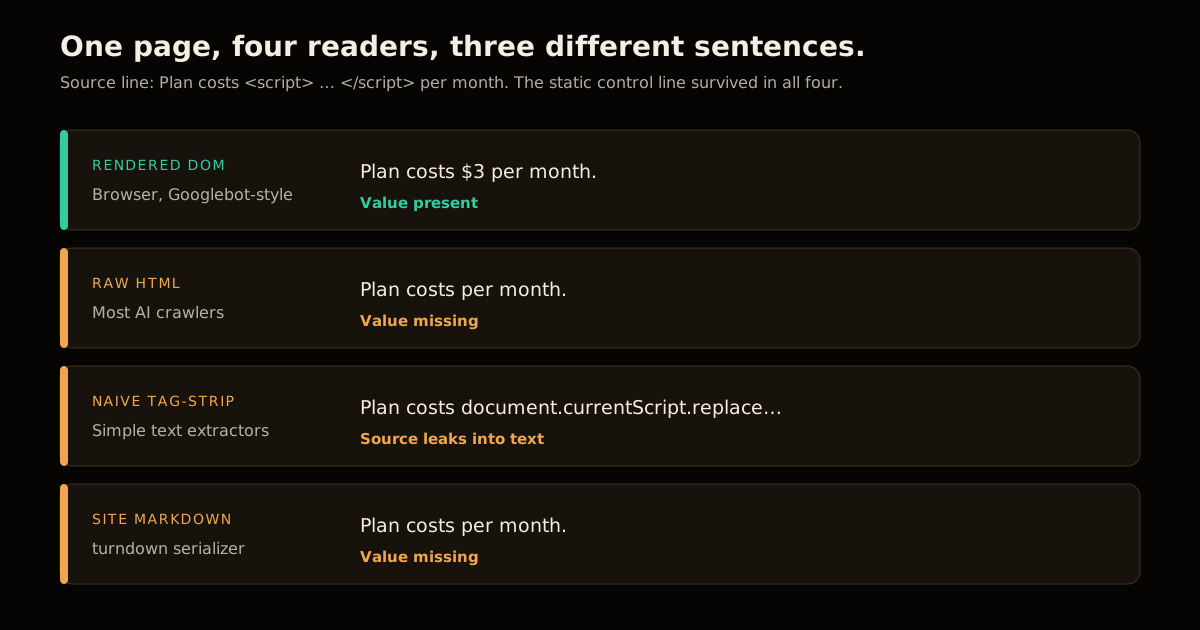
Who is in each row matters:
Googlebot belongs in the first row. Google’s JavaScript SEO basics say pages with a 200 status are queued for rendering by an evergreen Chromium and that “Google also uses the rendered HTML to index the page.” The same page says the render queue “can take longer” than a few seconds. So your inline text is eventually indexed, just not at first fetch.
AI crawlers belong in the second row. Vercel’s study of AI crawler traffic reports that “none of the major AI crawlers currently render JavaScript,” across 569 million GPTBot fetches and 370 million Claude fetches in a month. They fetch your script files and never run them.
Fetch tools for agents are the ones I cannot place. DeepSeek’s new fetch endpoint returns a page as Markdown at $0.75 per 1,000 successful requests, and its docs return a 404 for pages with “no extractable Markdown,” but they never say whether the fetcher executes JavaScript. I will not guess; treat any agent fetcher as the second or fourth row until its docs say otherwise. I cover making pages legible to those readers in How to Make Your Site Agent-Readable.
The practical rule: if the value would be wrong or missing when read from raw HTML, it is not safe for content that earns citations.
Does Inline Rendering Hurt Core Web Vitals?
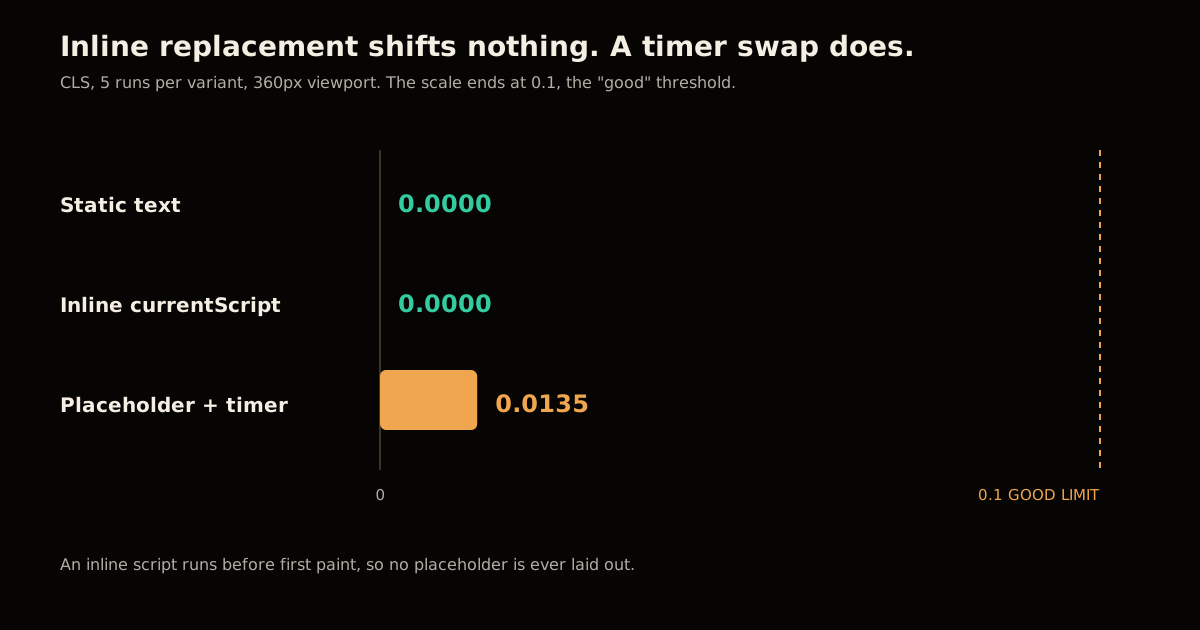
No, and this is the part of the pattern that deserves its reputation. I measured cumulative layout shift at a 360px viewport with a price line that wraps and pushes a heading down, five runs per variant:
| Variant | How the text arrives | CLS (5 runs) |
|---|---|---|
| Static text | In the HTML | 0.0000 on every run |
Inline currentScript | Replaced during parsing | 0.0000 on every run |
Placeholder … + setTimeout | Swapped 300 ms later | 0.0135 on every run |
An inline script runs synchronously while the parser is still building the DOM, before the first paint, so the browser never lays out a placeholder. The timer variant paints ”…”, then reflows. 0.0135 is under the 0.1 “good” threshold, but a real page with more content below the swap point shifts more. If you want the fuller Web Vitals picture, see the Core Web Vitals optimization guide.
The cost shows up elsewhere. Each call adds 22 bytes (<script>$("v123")</script> against v123) and a little parse work. At 1,000 inline scripts, median DOMContentLoaded went from 13.0 ms to 42.1 ms across seven runs, roughly 0.03 ms per script. At 100 scripts it was 12.3 ms against 14.0 ms. Cheap, but not free, and it scales linearly.
What Breaks If currentScript Is null?
document.currentScript is only valid while a classic script is first being processed. MDN says it “will not reference the [script] element if the code in the script is being called as a callback or event handler,” and for module scripts it points you to import.meta instead. I ran both cases against the helper:
| Where you call it | Result |
|---|---|
| Classic inline script, synchronous | Works: Build: v42 |
<script type="module"> | TypeError: Cannot read properties of null (reading 'replaceWith') |
Inside setTimeout | Same TypeError, and the text never appears |
Two consequences matter for production. A module script (or a framework bundling your inline code as one) silently loses the text. And if your CSP blocks inline scripts without a nonce, the page renders the same hole for every reader, humans included. Those failures are invisible in a quick local check.
How to Audit Inline Script Text in 4 Steps
You do not need to guess which of your pages depend on this. Compare what the server sends with what a browser builds.
- Fetch the raw HTML.
curl -s https://example.com/pricing > raw.html. This is what AI crawlers and most extractors read. - Render it in a real browser. With Playwright, call
page.goto(url)and readdocument.body.innerText. This is the Googlebot-style view. - Strip scripts from the raw HTML and diff the two texts. Anything that appears only in the rendered text was produced by JavaScript.
- Check your Markdown or text alternates. If you serve a
.mdrendering, confirm it contains the same facts. Mine did not, for the inline lines, which is exactly why I run this check.
// Fail CI when script-produced text carries a fact.
const raw = html.replace(/<script[sS]*?</script>/g, '').replace(/<[^>]+>/g, ' ');
const rendered = await page.evaluate(() => document.body.innerText);
const onlyRendered = rendered.split(/s+/).filter((w) => !raw.includes(w));
if (onlyRendered.length) console.warn('JS-only text:', onlyRendered.join(' '));
Anything this flags that is a price, version, date or product claim should move into the HTML. The agent-readability angle is the same one behind verifying AI crawlers by IP rather than user agent: decide who reads your page, then test as them.
When Is Inline Rendering Safe?
Match the technique to what the text is for:
| Use case | Inline currentScript | Better option |
|---|---|---|
| Copyright year | Safe | Fine either way; the year is not a quoted fact |
| Relative time (“3 min ago”) | Safe, with a static timestamp beside it | <time datetime> with real text |
| Locale-formatted number | Risky | Render the default at build time, enhance in the browser |
| Price, version, benchmark | Unsafe | Build-time substitution so it is plain HTML |
| Any sentence you want AI answers to cite | Unsafe | Plain HTML, plus a <noscript> fallback only for UI chrome |
For a statically generated site the answer is almost always build-time substitution: compute the value during the build and emit it as text. That is what this site does, and it is why the generated .md copies stay accurate. If you want to see how citations get decided once the page is readable, the GEO playbook and the ChatGPT site-scoping write-up are the next stops, and the AI search topic hub collects the rest.
My take: the technique is good engineering and bad content strategy. Keep it for decoration, and put every fact in the first response byte.
FAQ
Does Google index text inserted by document.currentScript.replaceWith?
Usually yes, because Googlebot renders pages with an evergreen Chromium and indexes the rendered HTML. The catch is the render queue, which Google says can take longer than a few seconds, so the text is not available at first crawl. Anything that must be indexed fast or quoted exactly belongs in the HTML itself.
Do AI crawlers execute inline scripts?
Vercel’s study of AI crawler traffic found that none of the major AI crawlers it measured render JavaScript, including OpenAI’s and Anthropic’s. They download script files but do not run them. A value produced by an inline script is therefore missing from what those crawlers read.
Does the pattern cause layout shift?
Not when the script runs during parsing. In my test at a 360px viewport, a synchronous inline replacement produced 0.0000 cumulative layout shift across five runs, the same as static text. A placeholder swapped by a timer produced 0.0135 every run.
Why does document.currentScript return null sometimes?
It only references the script element while that classic script is first being processed. It is null inside module scripts, and inside callbacks, timers and event handlers that run later. A helper like $ that reads it will throw a TypeError when called from any of those.
What should I use instead for prices, versions and dates?
Render them at build time so the value is plain text in the HTML. If a value must change in the browser, ship a correct static default and let script refine it. Reserve the self-replacing script for cosmetic text such as a copyright year.
Sources
- Inline rendering with document.currentScript, Lean Rada
- Inline rendering with document.currentScript, Simon Willison
- Understand JavaScript SEO basics, Google Search Central
- Document: currentScript property, MDN
- The rise of the AI crawler, Vercel
- DeepSeek Search and Fetch API docs
- First-party measurements: Chromium via Playwright, 5 runs for CLS and 7 runs for parse timing, 360px viewport, run on 2026-10-19.
Frequently asked questions
Google Search · Preferred sources
Prefer this site on Google
If you already read this writing, add umesh-malik.com as a Preferred Source. Google can then highlight it with a preferred badge in Top Stories, AI Overviews, and AI Mode — for you, not as a site-wide ranking boost.
Related Articles

Web Engineering
How to Increase SEO Traffic in the AI Era: 10 Techniques (2026)
How to increase SEO traffic in the AI era: 10 genuine, white-hat techniques anyone can use to earn clicks and citations from ChatGPT, Perplexity and AI Mode.

Web Engineering
SEO in the AI Era: The 2026 GEO Playbook for Winning AI Search Traffic
SEO in the AI era: what actually changed, why clicks fell 60%, and the GEO playbook to earn traffic from ChatGPT, Perplexity and Google AI Mode in 2026.

Web Engineering
React Server Components in 2026: The Mental Model, the use client Boundary & When Not to Use Them
React Server Components in 2026: the mental model that finally clicks, the use client boundary rules, and when NOT to use them — with the Web Vitals payoff.
Keep reading
Get new posts on AI, Claude Code & LLMs
New deep-dives on AI engineering, Claude Code, and developer tooling — follow along however you prefer.
About the Author
Software engineer writing about AI, Claude Code, LLMs, OpenAI, Anthropic, and developer tooling. 5+ years building production systems at Expedia Group, Tekion, and BYJU'S.