How to Review AI-Written Code You Don't Understand
How to review AI-written code you don't fully understand: sort changes into 3 risk tiers by path. In my repo 54% needed no human read. Here is the routing.

How to review AI-written code you don't fully understand: sort changes into 3 risk tiers by path. In my repo 54% needed no human read. Here is the routing.

Turnstile backend validation is the step most setups skip. The widget still renders while bots slip through unchecked. Here is how Spin fixes it, step by step.

How to build an autonomous cryptanalysis agent: the AI that broke a 1941 Enigma cipher unsolved since 2005, using a crib it found itself.

How to scope an AI agent for reverse engineering: one failing test beats a full spec. A GPU driver project shipped in 4 weeks, not years.

How to decide when to give an AI agent autonomy: chip design keeps 3 to 5 spec engineers per builder before trusting it — the same ratio tests your task.

How to build AI-generated code guardrails before shipping: the six checks Anthropic runs, what each catches, and the cost of running them on your own repo.

How to build an AI agent knowledge base: the wiki-plus-recipes pattern that cut per-turn tokens 80% and turned days of expert review into minutes.

Rust LSP low memory is achievable: Rust Glancer runs on 8GB machines by freezing analysis at save and offloading to disk.

Build a self-hosted AI coding agent with sandboxed execution. One prompt produces a repo, tests, CI, and deployed app — $25/mo, no cloud bills.

A Claude Code macOS printer driver project fixed a printer HP never supported — by diffing raw output byte-by-byte until a silent DPI mismatch turned up.

How to verify AI-generated benchmark claims: an LLM agent's regex engine beat Rust's regex crate by 1.4x on rebar, then lost 10x on a holdout it never saw.

Agent tool call cost jumped after you gave it better tools? GitHub hit that on Copilot code review and won ~20% back with a prompt rewrite, not new tools.

A research spike should ship as running code, not a design doc. alchemy-utils surfaced 8 engine blockers a doc would miss, and priced the fix at 3-5 weeks.

Learn complex topics with Claude Code by building a small simulation of the mechanism: the 4-step loop, the fact-check gate LLMs skip, and how to ship it free.

How to run Muse Glimmer 30B locally: the K-Quant setup that fits a single 24GB GPU, the drafter model that triples decode speed, and where it breaks.

Agent tool instructions decide what your agent costs. GitHub kept the same grep/glob/view toolset, rewrote the guidance, and cut review cost by ~20%.

Run CI/CD on Cloudflare Workflows and a GitHub Actions YAML becomes 18 lines of TypeScript. Which meter bills first, and what private beta still blocks.

The Rust LLM policy bans AI-created code and prose but allows AI review, analysis, and bug-finding. Here's the exact rule, why it works, and how to copy it.

I ran Claude Code auto mode in production for a week — where it's reliable, where it broke, real token costs from my usage logs, and my honest verdict.

Claude Code vs Cursor for production, field-tested on real shipping tasks: a working engineer's decision table, failure modes, pricing, and which to use when.

The honest answer to using Claude Code and Codex for free in 2026: what's truly $0, what isn't, the best free AI coding CLIs, and how to cut your bill.

Claude Fable 5 in auto mode built my entire HLS streaming microservice in under a day — AWS infra, security, backend, frontend, CI/CD, migrations, runbooks.

Cursor vs Claude Code vs Copilot in 2026 — how they actually differ in model, workflow, and autonomy, and which to use for what (I use all three).

How to write a CLAUDE.md that actually helps Claude Code: what to include, what to leave out, a real structure, and how to stop it from rotting.

claude-swap is an open-source CLI that switches Claude Code accounts in seconds — no browser re-login. How it works, how to use it, and what it misses.

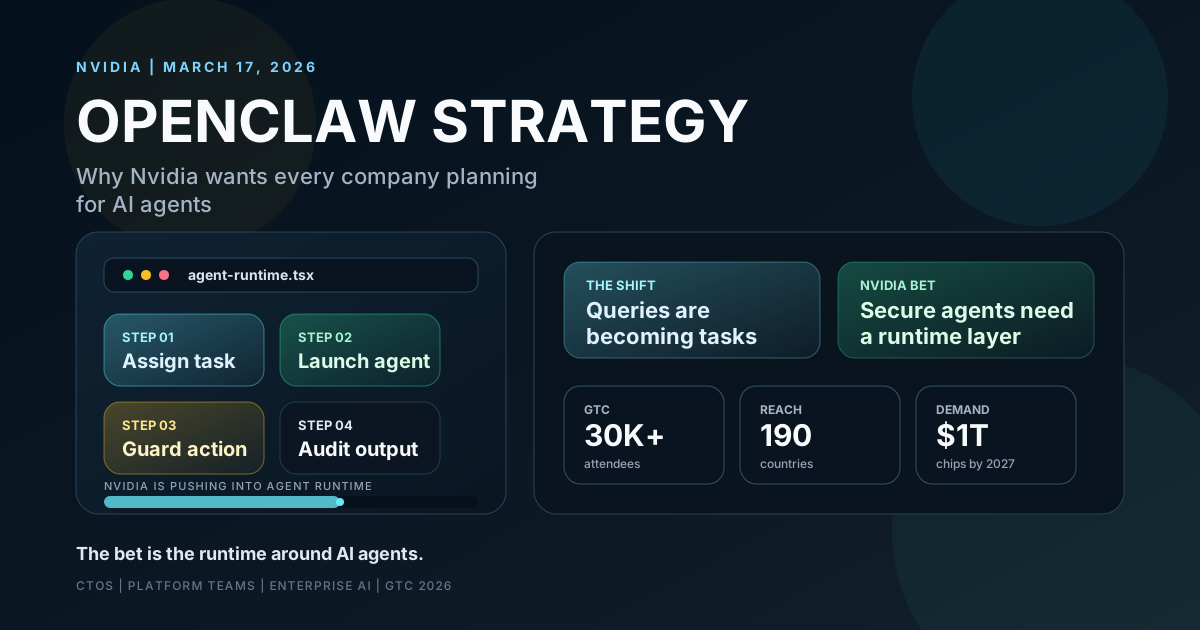
At GTC 2026, Jensen Huang said every company needs a Nvidia OpenClaw strategy. Here is what it means and what U.S. teams should do next.

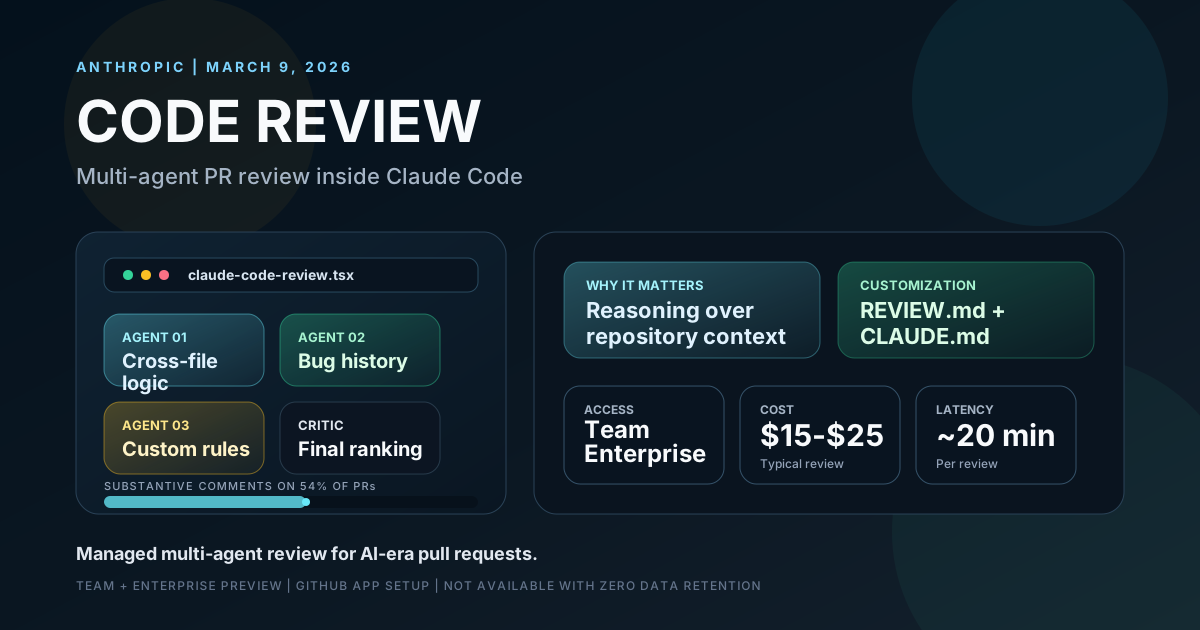
Anthropic's Claude Code Review runs multi-agent PR reviews for $15-$25 each. How it works, pricing, REVIEW.md setup, and where it beats linters.

A 2026 guide to Figma to React conversion with OpenAI Codex: setup, prompts, component structure, and real production examples.

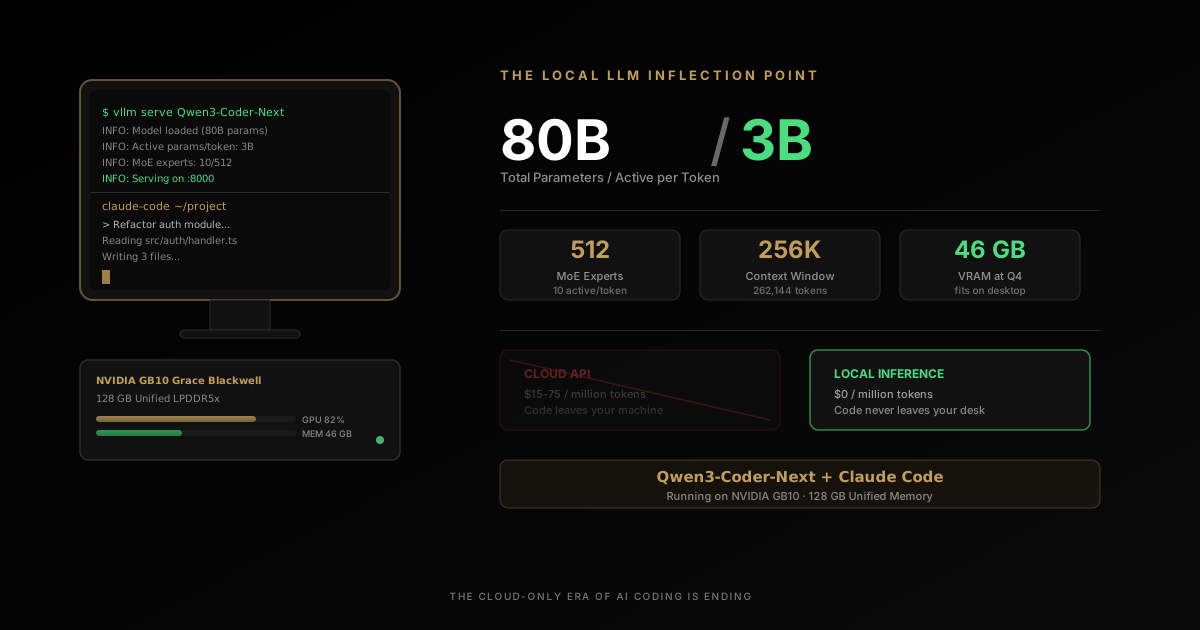
Qwen3-Coder runs 80B parameters on a desktop with only 3B active per token — and plugs into Claude Code. Why the cloud-only era of AI coding is ending.

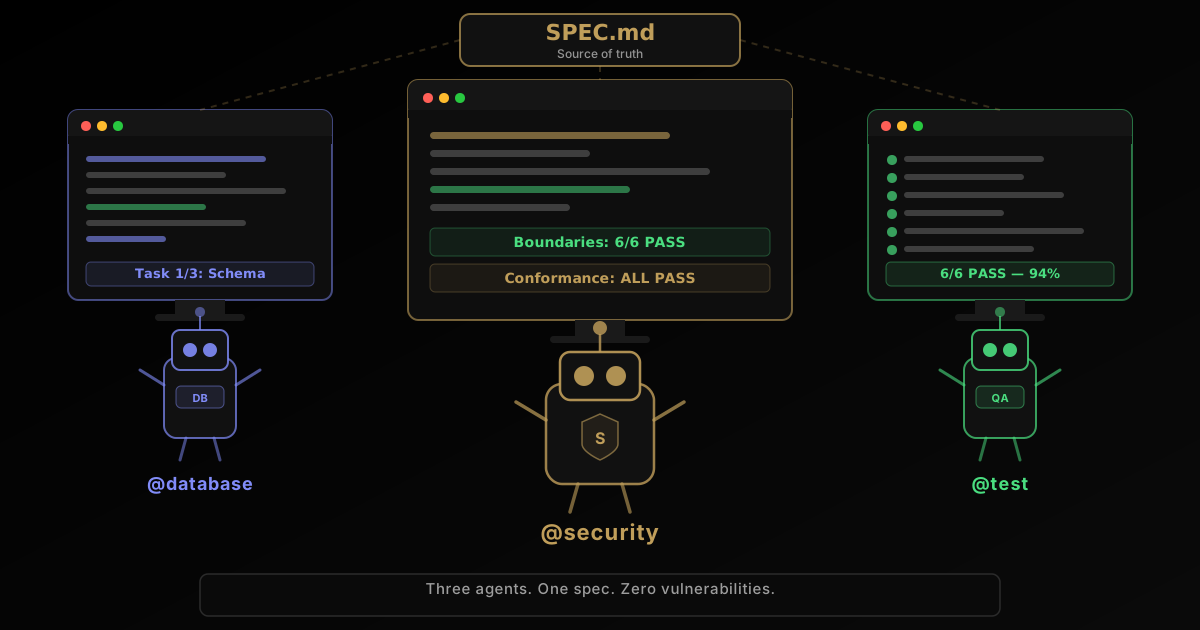
Why AI coding agent prompts fail — and how spec-driven development fixes it, per Addy Osmani's 5-principle framework backed by GitHub's 2,500-config analysis.

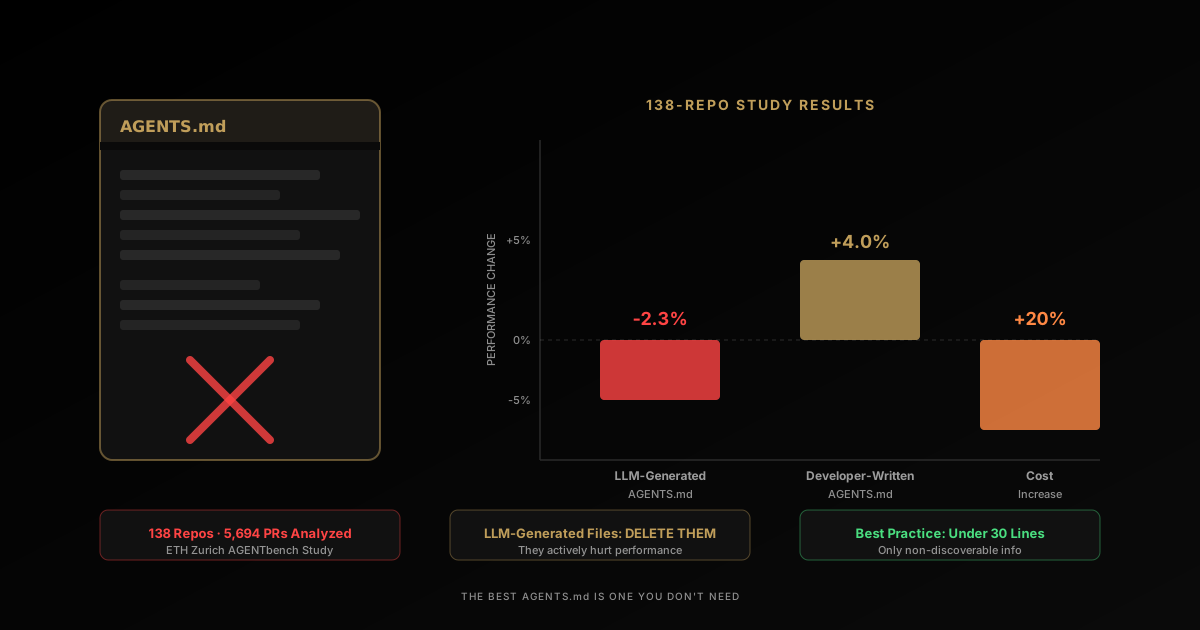
A 138-repo study: AGENTS.md files hurt performance by 2-3% and raised costs 20%+. What the research found — and what actually works instead.